F. Tokuda, S. Arai and K. Kosuge, “Convolutional Neural Network-Based Visual Servoing for Eye-to-Hand Manipulator,” IEEE Access, vol. 9, pp. 91820-91835, 2021.
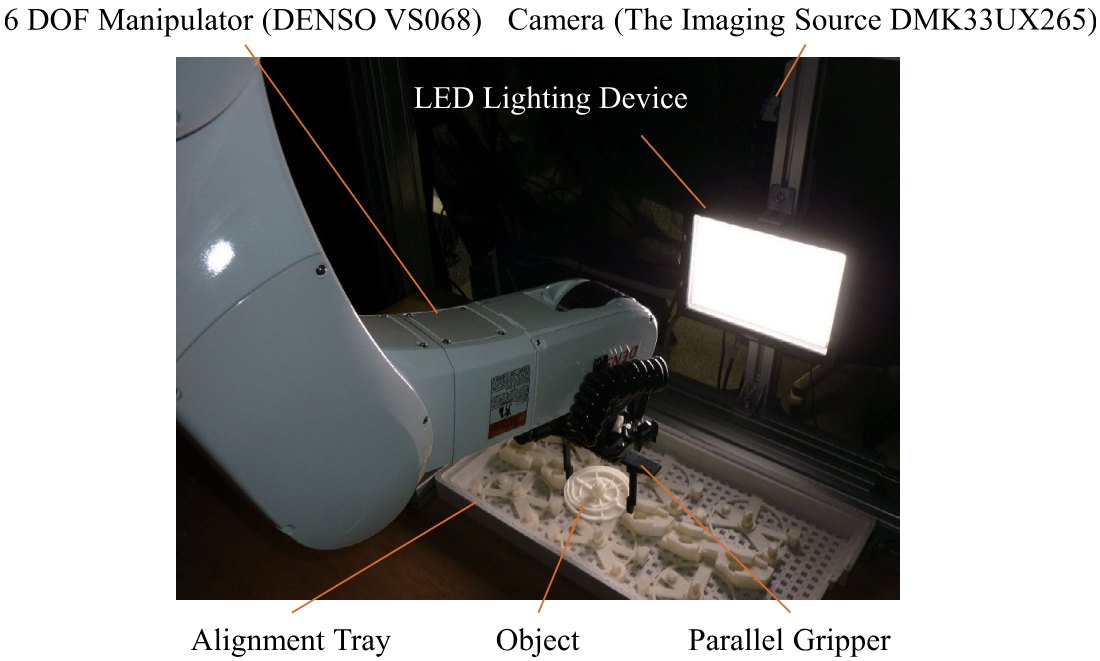
Bringing an object to a target pose requires relating changes in the camera image to robot motion. In this work that relation was learned from images taken by a camera fixed outside the robot (eye-to-hand).
The proposed DEFINet encodes the target and current images with weight-shared CNNs and regresses the relative pose from the difference between their features. Training pairs of images and motions were collected by moving the robot.
Positioning was evaluated in simulation and on a real six-axis industrial robot. The work started with a 2019 paper in the SICE Transactions and was extended in the 2021 IEEE Access article.
Video
If the video does not load, open it in Google Drive.
Related first-author paper (in Japanese): F. Tokuda, S. Arai and K. Kosuge, “Object positioning by visual servoing based on deep learning,” Transactions of SICE, vol. 55, no. 11, pp. 717-725, 2019.